
On Thursday, November 12, just after one in the afternoon in Santiago, a lot of people noticed Outlook wouldn't load. Shortly after, Teams, OneDrive, Copilot, and the admin consoles weren't working properly either. What started as "email is down" ended up, in the words of TechCrunch, turning into a global Microsoft cloud crisis. Exchange Online was down for almost 24 hours.
On Sunday the 15th, Microsoft sent customers a preliminary incident report. Based on what The Register and TechCentral report, it's a document that any team operating critical systems should discuss. Not out of morbid curiosity about watching a giant fall, but because almost everything that went wrong there could happen to us, at any scale.
What happened, in order
I'll summarize the sequence based on what both outlets report, citing the incident report:
- July 2026. Microsoft prepares a specific change for the servers of a network gateway that sits in front of many Microsoft 365 services: it receives user connections and passes them on to Exchange and friends. The change passes load testing and is rolled out in stages worldwide. According to the report, for more than three months it operated "without impact."
- The defect nobody saw. Under certain loads, the change caused lock contention within an internal Windows process: tasks waiting on each other until CPU and memory were exhausted. The problem gets worse on newer machines with more cores. And the load tests, Microsoft admits, "tended to focus on weaker hardware, with fewer cores."
- Two normal conditions at the same time. In the early morning of the 12th (UTC time), Teams traffic automatically moved from an alternate gateway to the primary gateway that also serves Exchange Online, something Microsoft describes as a normal part of operations. On top of that, around 14% of that gateway's capacity was out of service due to an unrelated issue from the previous day. Neither of these things, on its own, was a problem.
- The cascade. With more load and fewer servers, the defect was triggered during US peak hours. Servers that stopped responding were pulled out of rotation, and their traffic went to the healthy ones, which then went down for the same reason. In under two hours, more than 80% of the gateway's servers were unresponsive. The barriers between cells, designed precisely so a local failure doesn't spread, didn't hold up "due to a separate issue" that the preliminary report doesn't explain.
- The recovery that didn't recover. Every server that came back was immediately crushed by the accumulated traffic and went down again. The automated recovery processes "were not designed to restore service from this state." And since the faulty change was months old, the usual rollback tools couldn't undo it quickly.
- The way out. About 15 hours after the first alert, engineers began applying an update that reverted that code path to its previous state, server group by server group, prioritizing regions entering business hours.
Teams, OneDrive, and SharePoint were able to route their traffic away from the troubled gateway and recovered sooner. Exchange Online couldn't, "for reasons of scale."
A latent failure is not just another bug
What makes me think the most about this incident is point 1. We're used to associating incidents with the latest change: something breaks, we look at what was deployed in the last few hours, and we revert it. Canary deployments, post-deploy monitoring, and the rollback button are all built for that.
A latent failure breaks that model. The change passed every gate. The staged rollout didn't catch anything because there was nothing to catch given the load during those days. And when the failure finally showed up, the change was no longer "recent": dozens of other changes had piled on top of it, and it wasn't obvious which one was the culprit. In fact, it took Microsoft several hours to identify that the problem was in connection negotiation.
The uncomfortable lesson is that progressive rollout validates a change against the load that occurred during the rollout, not against the load that could occur. If the defect only shows up in the 99.9th percentile of conditions (traffic peak, reduced capacity, failover in progress), the canary won't see it. Production will — on the worst possible day.
Homogeneous redundancy: failover as a contagion vector
The second point is better known, but here it played out very cleanly. Failover worked exactly as designed: a node stops responding, its traffic gets distributed among the healthy ones. The problem is that every node had the same defect. Spreading load across identical servers that fail from overload isn't redundancy; it's an efficient way to spread the failure.
It's the same idea of common failure modes I discussed about the Google Cloud outage in London, but this time the shared component was a line of code.
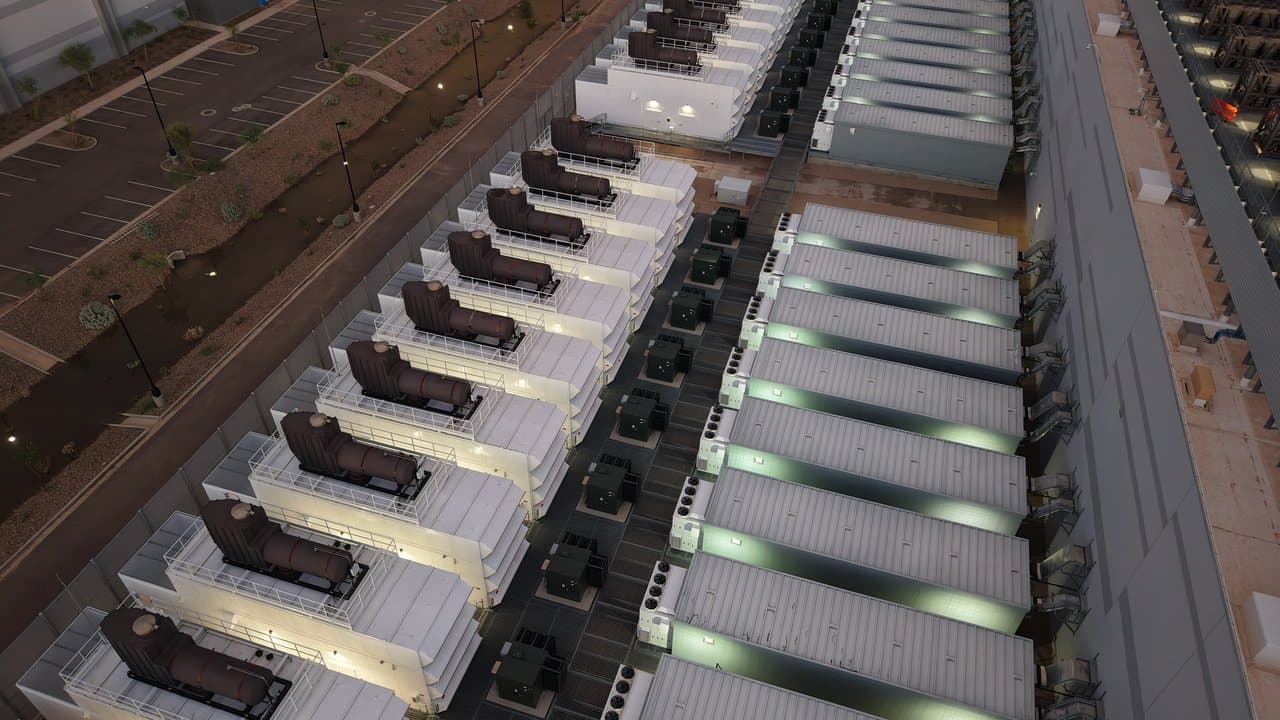
Identical servers, row after row, in Fermilab's computing center. Photo: U.S. Department of Energy, public domain, via Wikimedia Commons.
That diagram has two cycles, and both reinforce themselves. It's what in distributed systems is known as a metastable state: once the system enters it, it only exits if someone breaks the cycle from the outside, even though the original cause (that bit of extra load) is already gone. Adding capacity, which was attempted overnight, isn't enough if every new server enters the same cycle.
Rollback has an expiration date
The third point is the one I think most teams underestimate. "If something goes wrong, we roll back" is a phrase I've heard in plenty of change advisory boards. It works fine for the first few hours or days. But a rollback depends on the previous state still existing and still being compatible with everything deployed after it. As the weeks go by, reverting a change stops being a matter of pressing a button and becomes a new piece of development, with its own risk.
Microsoft ended up doing exactly that: a patch that reverted the code to its previous behavior. In the middle of a global incident, with the whole world watching.
What I'd bring to the table
The takeaway isn't "let's stop using SaaS." Any organization operating at scale has dormant defects in production right now. What I would propose to any team operating something critical:
Load-test on the hardware that actually runs in production. The performance testing environment is usually the poor relative: older, smaller machines, "to save money." Here the defect was worse precisely on the newest hardware.
Test the combinations, not just the scenarios. "We lose 14% of capacity" and "failover traffic arrives" were probably each in some test plan. What kills you is the conjunction. Chaos exercises and load tests should include compound scenarios: reduced capacity plus peak plus failover.
Put limits on failover. A system that redistributes load with no ceiling can turn a partial failure into a total one. It's better for healthy nodes to reject work (load shedding, admission control) than to accept everything and go down. This is, in fact, one of the measures Microsoft says it took after the incident: limiting how load gets redistributed to avoid another cascade.
Design for cold start. The question "how do we bring the service back up if 80% of the fleet is down and there's a huge queue waiting?" deserves its own runbook and, if possible, its own mechanism: gradual traffic readmission, priorities, the option to keep nodes out of rotation until they're stable.
Changes reversible by design, not by rollback. For changes to critical components, wrap the new behavior in a feature flag or a code path that can be disabled months later without redeploying. It's more work up front, but it turns the "patch of the patch" into a configuration change.
Verify that cells actually isolate. Here the barriers existed and didn't work. That's not something you discover from a diagram — you discover it by deliberately breaking a cell.
Know which of your dependencies can't failover. Exchange couldn't get off the gateway for reasons of scale. In our own architecture there are almost always one or two components like that. It's worth having them identified, with a degradation plan, because they're what determines how long the incident lasts.
The question for the provider and the question for ourselves
One last revealing detail: according to TechCentral, Exchange Online's SLA credits are calculated based on the monthly fee, are the "sole and exclusive remedy," and don't cover losses. The provider gives you back part of what you paid, not what you lost. That's standard in the industry, and a good reminder that an SLA is not a continuity plan.
We should demand transparency and post-incident reports from providers. But the question most worth asking isn't "why did Microsoft fail?" but "what dormant failure do I have in production, and what combination of ordinary days is going to wake it up?" As I wrote a while back, designing for failure isn't pessimism: it's assuming the bad day will come and deciding ahead of time how we want the system to behave when it does.
Microsoft promised the final report for November 20. I'll be reading it looking for that "separate issue" that let the cascade spread between cells: that, I suspect, is where the most valuable lesson lies.